Discovery & data audit
We start with the decision you need to make, the data you have, and your constraints.
- Problem framing & success metrics
- Data quality review
- Analysis plan & experiment design
We help teams figure out which models, methods, and bets are worth making. That means experiments, benchmarking, failure analysis, and technical recommendations grounded in evidence.
Bring us a question, a dataset, or a rough prototype. Most projects go from question to answer in 4 to 12 weeks.

Our work spans AI products, scientific research, consumer hardware, and program evaluation.
Rapid exploration, baseline comparisons, and hard-nosed feasibility checks. See our work.
Prompting, rubric design, reliability testing, and failure analysis. Learn about our LLM chatbot work.
Offline/online metrics, ranking experiments, and user-impact analysis. Read our search engine case study.
We clean messy data, find meaningful patterns, and test hypotheses, even on small datasets. Explore our small-dataset benchmarks.
We compare models and quantify uncertainty.
Independent evaluation of models and methods before you commit.
We run 4–12 week research sprints. You get clear answers backed by experiments, benchmarks, and documented methods.
We start with the decision you need to make, the data you have, and your constraints.
We compare baselines and test approaches head-to-head.
We write up what worked, what didn’t, and what to do next.
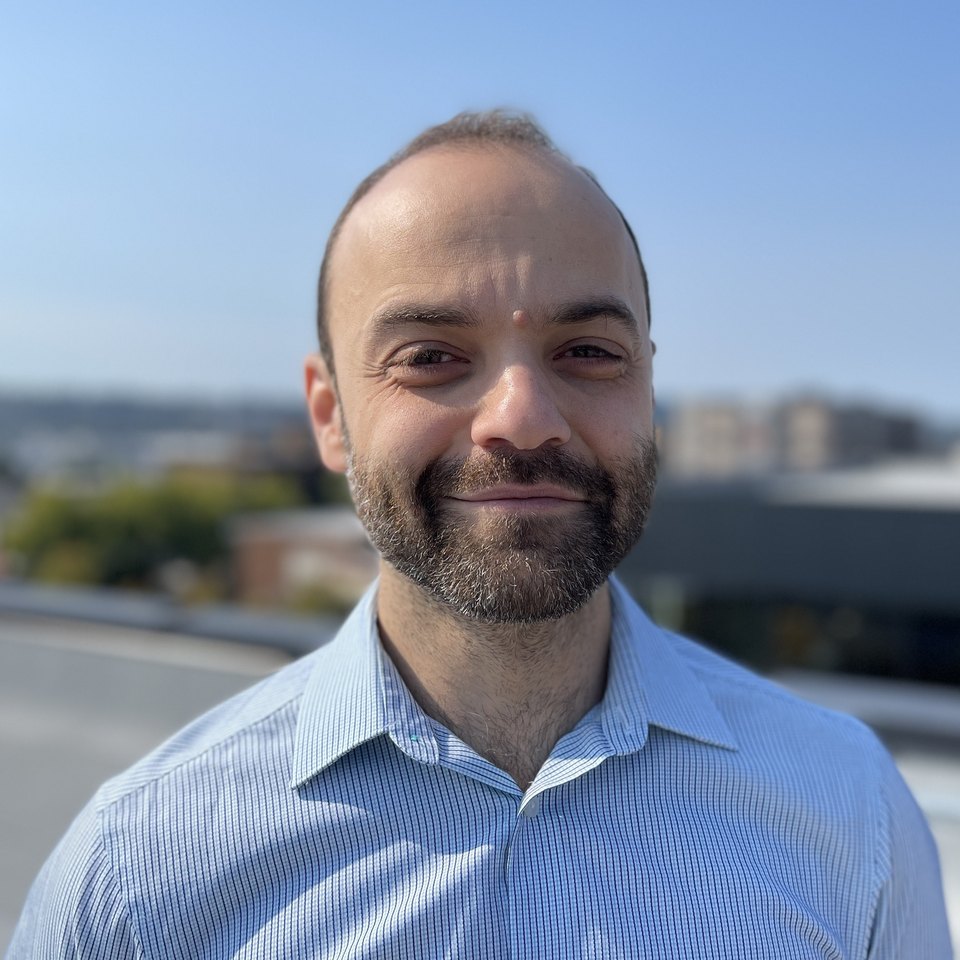
Sergey Feldman is a Principal Research Scientist at the Allen Institute for AI (Ai2). Previously, he served as Head of AI at Alongside, a youth well-being platform acquired by TimelyCare in 2026. He has led research and development for large-scale AI, retrieval, and language systems, including work behind Semantic Scholar and Asta. His expertise spans LLMs, machine learning, natural language processing, and scientific document analysis.
Sergey founded Data Cowboys to bring research-grade thinking, honest evaluation, and clear communication to organizations solving hard problems. He holds a PhD in machine learning from the University of Washington and has been building AI systems since 2007.
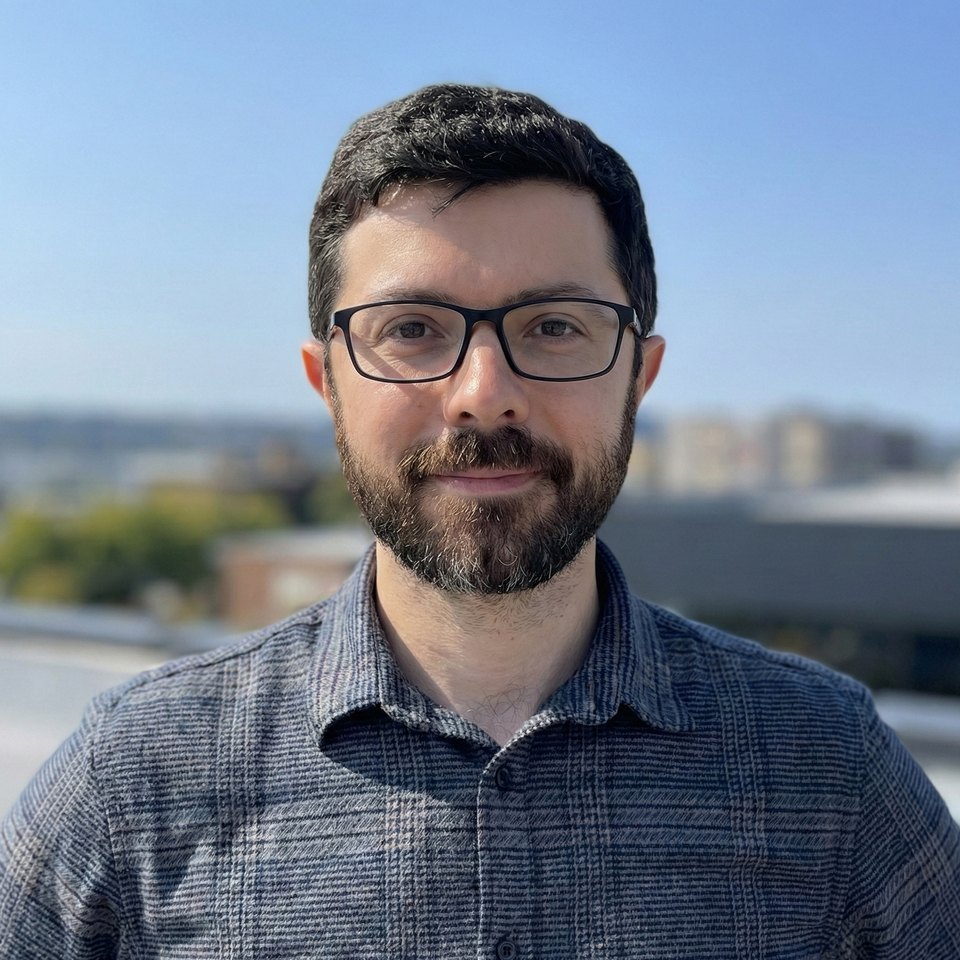
Ilya Barshai is a Principal Research Scientist at McGraw Hill, where he applies AI and machine learning to educational technology. He brings over a decade of hands-on data science experience.
Ilya joined Data Cowboys in 2016, bringing a practitioner’s eye for what actually works: rigorous analysis, careful modeling, and straight answers. Before moving into data science, he spent eight years in risk and failure analysis of electromechanical product designs.
Sergey and Ilya grasped what we do the fastest of anyone I’ve explained our startup to. They are professional, timely, and so fast with their thinking and output.
Sergey has a wonderful knack for quickly scoping a problem, making efficient decisions on model choice and parameters, and clearly communicating throughout the process.
Sergey Feldman is brilliant, collaborative, candid, and lightning-fast. He has a special gift for explaining complex analytical concepts in terms anyone can understand.
Sergey provides well-considered results quickly with in-depth knowledge communicated clearly to readers at every level.
Data Cowboys’ work has been incredible. We understand our data, verify our impact, and keep people safe from exploitation.
We tested 108 small datasets to see what really works.
Why two models with the same held-out score can still behave very differently in production.
How we improved Semantic Scholar search using three years of logs.
Making ML results understandable to collaborators.
On building an AI career, evaluation, and lessons from research.
Discussion on machine learning for search, consulting for the Gates Foundation, AI for mental health, and career lessons.
Predicting child mortality with the CHAIN network using XGBoost and SHAP values to identify key physiological drivers for targeted interventions.
Nested cross-validation for model selection and performance estimation on small datasets.
Let’s figure out what the evidence says before you commit more time and budget.
Want to email instead? Reach us at ilya@data-cowboys.com.